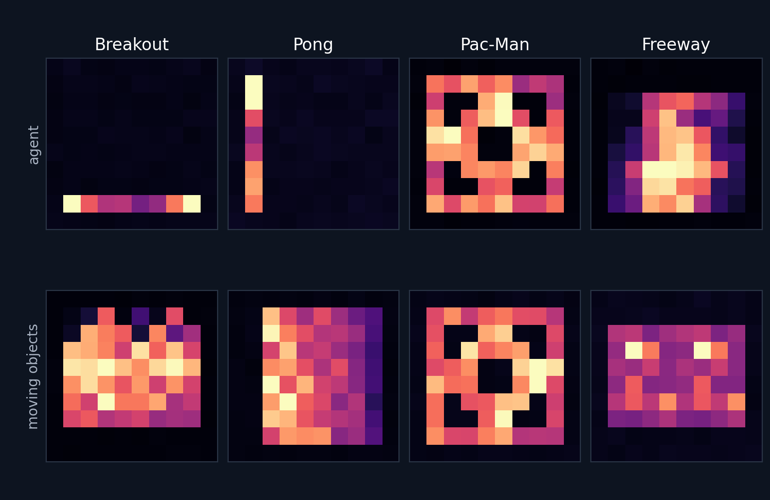
First-layer weight strength by grid cell for the four game networks GPT-6 Astra identified from raw weights (top: agent channel; bottom: moving objects). Graphic: R&D World. Data: Takehi et al., MIT CSAIL (CC BY 4.0)
OpenAI’s current frontier model GPT-6 Astra could have a knack for understanding and writing neural network weights of other models, based on recently announced research from a team at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL). In its headline experiment, Astra targeted 131,072 of the 0.8 billion weights in Alibaba’s open-weight model Qwen3.5-0.8B, 0.016% of the total, and the model’s score on the MATH-500 benchmark rose from 7.9% to 48.1%. If frontier models can read and rewrite other networks this way, labs could audit models for hidden flaws and patch them without new training runs, one of the uses the authors highlighted in their research.
Within a day, two developers, Matthew Honnibal and Sean Goedecke, had published critiques of the CSAIL research. Both argue that the most prominent result in the research came from the type of Python analysis a human machine-learning engineer would write. Honnibal argues that the announcement groups experiments using different levels of tool access under one broad claim. Goedecke describes the Qwen fix as an application of steering, an existing technique for changing model behavior.
The authors of the CSAIL research, Rikiya Takehi, Jayden Teoh, Alex Zhang and Omar Khattab, posted the results on Nov. 2 as a blog post, “Sparks of Weight-Space Programming,” with logs for the reported experiments on GitHub and the edited Qwen model on Hugging Face. The post also drew a lengthy thread on Hacker News, including arguments that the research is not as groundbreaking as the announcement made it seem to be.
What the authors claim Astra did
The team reported eight experiments and a follow-up with Google’s Gemma 3 270M. The researchers started with small networks and ended with real language models. In the smallest, Astra received the 17,253 raw weights of a game-playing network as text, with no tools, and named the game it had been trained on. It did this for all four networks. It also identified the shapes three small diffusion models drew and, given a stuck driving policy, a scene description and one recorded failure episode, rewrote 3.5% of its weights so the simulated car cleared a ramp in all 1,024 test runs.
The original car-control policy (faded) and Astra’s edited policy.
Animation: Takehi et al., MIT CSAIL.
In the headline Qwen run, Astra worked in a Python session with the model’s weights loaded and could run up to 50 batches of practice evaluations using problems from GSM8K and MATH, two commonly used standard datasets and benchmarks in AI designed to evaluate the multi-step mathematical reasoning capabilities of LLMs. In the study, each permitted call could generate answers to up to 512 problems or inspect internal activity on up to 1,024 texts. It found that the base model looped: 85 of its first 96 practice answers ran to the 32,768-token limit without reaching an answer, a weakness Qwen’s model card notes. The experiment enabled thinking mode; the model defaults to non-thinking mode. Astra traced the looping to one direction written by the feed-forward layers in blocks 15 and 19 and subtracted it from 64 output columns in each. The edit targeted 131,072 weights; 130,188 actually differed after rounding to the precision used for evaluation, according to the experiment README. The successful run involved 80 Python executions over 20.3 elapsed hours, including a 4.7-hour service interruption.
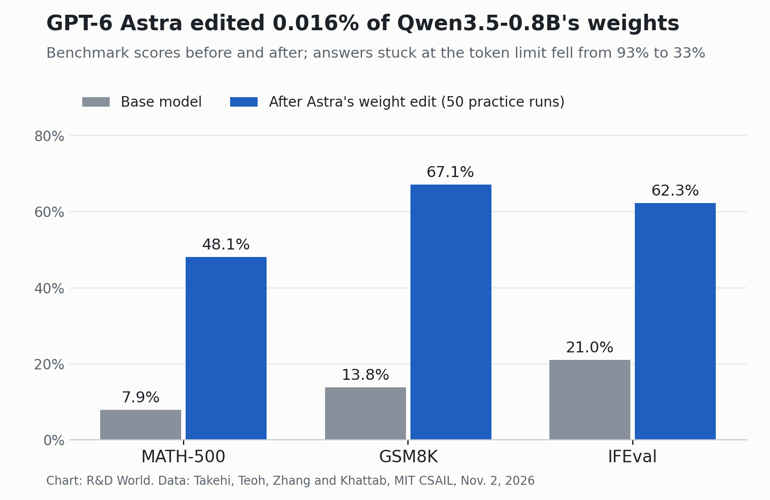
Chart: R&D World. Data: Takehi et al., MIT CSAIL
| Qwen3.5-0.8B | MATH-500 | GSM8K | IFEval | MATH-500 answers that hit the token limit |
|---|---|---|---|---|
| Base model | 7.9% | 13.8% | 21.0% | 93.0% |
| Edited, 10 practice batches | 12.3% | 25.7% | 49.0% | 87.2% |
| Edited, 25 practice batches | 14.1% | 25.1% | 39.9% | 86.4% |
| Edited, 50 practice batches | 48.1% | 67.1% | 62.3% | 33.1% |
Source: Takehi et al., MIT CSAIL, Nov. 2, 2026. Thinking mode enabled. The harness withheld the evaluation questions and results during editing. Each edited row is a separate run with a different edit; the 131,072-weight edit described above is the 50-batch run.
The checkpoint’s model card also reports a separate rerun by Hugging Face’s akhaliq using ML Intern. Across 2,000 generations covering all 500 MATH-500 problems, the edited model scored 51.0%, with 31.6% of answers hitting the token limit.
The researchers also tried Gemma 3 270M, a smaller model that rarely loops: 8.5% of its MATH-500 answers hit its token limit, versus 93% for Qwen. The authors reported no established improvement in these runs. Its edits moved Gemma’s MATH-500 score from 6.8% to at most 7.7%, a gain Astra reported as not established. The authors’ reading: a weight edit can clear an obstacle that hides an ability, but here it could not add an ability Gemma lacked.
| Experiment | Network size | What Astra had | Result |
|---|---|---|---|
| Name the game a network plays | 17,253 weights | Raw weights as text | 4 of 4 correct |
| Name the shape a diffusion model draws | 23,824 | Raw weights as text | 3 of 3 correct |
| Name a small language model’s training text | 7.2 million | Python on the middle layers | 3 of 3 correct |
| Fix a stuck driving policy | 171,664 | Raw weights, scene description and one recorded failure episode | 0% to 100% success |
| Write game networks from scratch | about 20,000 | Game rules and code | Beat PPO after 100 million steps in all three games; beat 500-million-step PPO only in Breakout |
| Write a 9×9 Go network | 1.48 million | Python, up to 50 practice runs | Beat an equal-sized PPO network |
| Spot the sycophantic model | 270 million | Python; then attention patterns | Failed; then 3 of 3 |
| Fix Qwen’s math | 0.8 billion | Python, up to 50 practice batches | 7.9% to 48.1% on MATH-500 |
| Raise Gemma’s math | 270 million | Python, up to 50 practice batches | No established gain (at most 0.9 percentage points) |
Compiled by R&D World from Takehi et al.; the access breakdown follows Honnibal’s sorting.
What labs could do with the research
According to the authors, a model that can read weights could audit another for backdoors or hidden capabilities without running benchmarks. Targeted edits could replace some fine-tuning runs, and because they touch few weights, they could avoid the forgetting that fine-tuning often causes. The authors also propose support for recursive self-improvement applications. The team says it is building a benchmark and a harness to measure the capability.
Agent coordination has already produced unexpected behavior elsewhere. In its Aug. 26 account of the Hugging Face incident, OpenAI described agents operating with reduced safeguards that used shared infrastructure to exchange messages, share exploits and delegate work during July cybersecurity evaluations. An internal research model called IM1 drove the main compromise; OpenAI explicitly excluded Astra from the incident.
Combining that kind of coordination with weight editing suggests a possible further step: agents with access to model weights could divide up the work of diagnosing a model, proposing edits and testing the resulting behavior. That combined workflow remains a hypothesis. The MIT team’s demonstrated language-model edit targeted Qwen; extending the approach to an agent changing its own underlying model remains a proposed application.
Astra has drawn attention for its benchmark results before. In September, the ARC Prize Foundation scored it at 62.7% on ARC-AGI-3 under a shared harness, and OpenAI said Astra had met its Critical cyber-capability threshold. R&D World compared it with Kimi K3.1 Pro and Claude Opus 5.5 on Oct. 23.
Tell Us What You Think!
You must be logged in to post a comment.