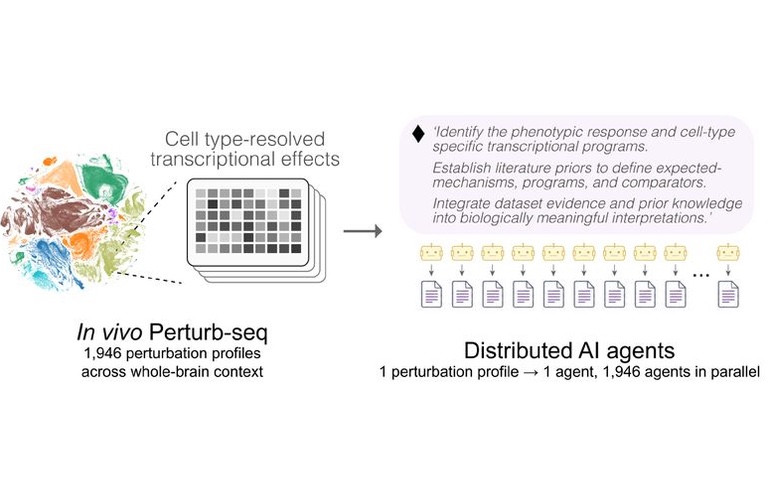
Image: Sun et al., bioRxiv (2026), CC BY 4.0.
Scientists cannot summon a thousand colleagues to tackle a problem at a moment’s notice. AI systems increasingly can assemble the digital equivalent. OpenAI now reports using thousands of AI agents to analyze biological data and generate hypotheses for scientists to test.
The announcement follows OpenAI’s introduction earlier this year of GPT-Rosalind, a model specialized for life sciences research.
OpenAI, drug-discovery-focused PerturbAI and Scripps Research said Oct. 21 that 1,946 GPT-Rosalind agents, running in parallel, analyzed existing data from millions of mouse brain cells in 32 minutes. The team estimates that comparable human analysis and literature review would take months to a year, an illustrative figure the authors built from assumed times of 15 minutes per gene disruption and 10 minutes per paper read.
The work, described in a bioRxiv preprint, applies an approach the team calls distributed biological reasoning to a whole-brain CRISPR atlas. Such experiments let researchers disrupt genes and measure the resulting changes in cells. These experiments can generate more observations than a team can readily investigate in depth.
That gap is one reason researchers share cell atlases. “We build cell atlases so that other scientists can make discoveries we haven’t imagined yet,” Sarah Teichmann, chair in stem cell medicine at the University of Cambridge and founding co-chair of the Human Cell Atlas, said in OpenAI’s announcement. “AI could help more researchers explore these resources and turn unexpected observations into new questions to test.”
The researchers’ software assigns each gene disruption to an independent agent, which examines the cellular changes, searches the literature and proposes explanations. The system combines their reports to identify connections and rank ideas for follow-up.
The research offers a proof of concept for a scientist using hundreds or thousands of agents to review literature and interpret results in parallel. In a comparison using the same model, prompt, tools and data access, the single-agent runs averaged about 11 references at the largest workload. The distributed agents retained 7,586 references, approximately 711 times as many, according to the project’s public data.
To assess the reports, the team recruited 30 doctoral-level biologists for a blinded review. Their assessments broadly supported the agents’ rankings of promising research leads. The agents also matched or refined 48 of the original atlas study’s 55 findings that could be drawn from the data they received, while working without access to that study’s manuscript. The human reviewers graded the agents’ reports; the comparison with human analysts rests on the time estimate above.
The study’s single-agent baseline also generated a lead that interested the experts. Disrupting DCTN1, a gene linked to neurodegeneration, increased activity in genes involved in cholesterol production. The baseline agent proposed that problems moving cholesterol within neurons might prompt the cells to make more. Three blinded reviewers gave the finding an average follow-up priority score of 4.3 out of 5.
Tomasz Nowakowski, an associate professor of neurological surgery at UCSF who is not an author of the preprint, said in OpenAI’s announcement that the cholesterol lead shows why linking findings across disciplines matters. “Sometimes the clues are already there, scattered across different fields—we just haven’t connected them,” he said.
In the long run, the authors envision a repeating cycle where researchers run a screen, agents interpret the results, and predictive models help identify gene disruptions worth testing next. New measurements would then refine the predictions and interpretations. They also propose extending the approach to data on proteins, cell shape and tissue organization, giving researchers a broader set of connections to investigate with each experiment.
Scientists would still make the decisive calls in that loop, the authors argue. “Reading the literature, weighing explanations, and choosing decisive experiments would remain central to scientific training and judgment,” they write, “while agents broaden the questions researchers can pursue.”
Tell Us What You Think!
You must be logged in to post a comment.